Radar Telegram alerts Open Radar

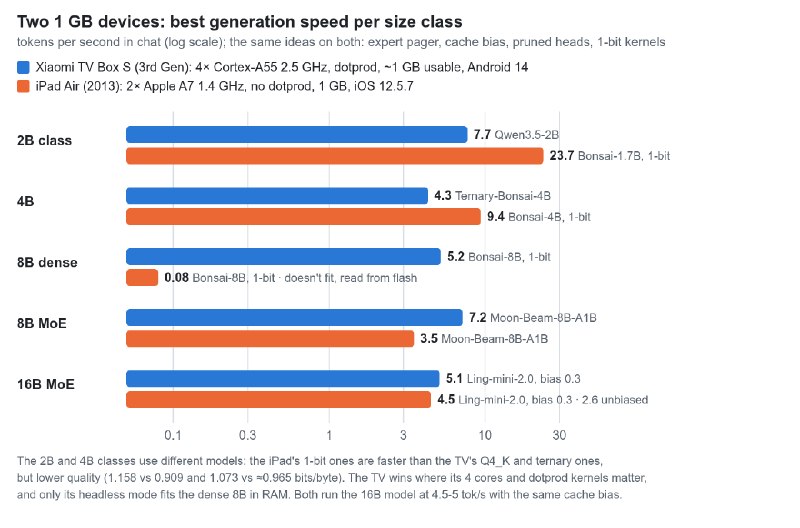
In the open project smolmaxxing, a model with 80 billion parameters was launched on the phone. On OnePlus Nord CE 2 from 2022, Qwen3-Next-80B-A3B issues 2.6-3.1 tokens per second with about 5GB memory peak, Qwen3.6-35B-A3B 4.9-5.7. The lower digits are obtained with precise routing, and the upper ones with a slight shift of the router in favor of experts already in memory: in the 80B model, 0.5% paraflexia increases. The measurements were performed in the context of 1,024 tokens on responses of 160 tokens each. On the Xiaomi set-top box and the iPad Air 2013, where no more than 1GB is available for the program, the same techniques are used to launch Model 16B Ling-mini-2.0 speeds in the graph.

תרגם לעברית

Нейроканал (RU) · · Source

In the open project smolmaxxing, a model with 80 billion parameters was launched on the phone. On OnePlus Nord CE 2 from 2022, Qwen3-Next-80B-A3B issues 2.6-3.1 tokens per second with about 5GB memory peak, Qwen3.6-35B-A3B 4.9-5.7. The lower digits are obtained with precise routing, and the upper ones with a slight shift of the router in favor of experts already in memory: in the 80B model, 0.5% paraflexia increases. The measurements were performed in the context of 1,024 tokens on responses of 160 tokens each. On the Xiaomi set-top box and the iPad Air 2013, where no more than 1GB is available for the program, the same techniques are used to launch Model 16B Ling-mini-2.0 speeds in the graph.

In the open project smolmaxxing, a model with 80 billion parameters was launched on the phone. On OnePlus Nord CE 2 from 2022, Qwen3-Next-80B-A3B issues 2.6-3.1 tokens per second with about 5GB memory peak, Qwen3.6-35B-A3B 4.9-5.7. The lower digits are obtained with precise routing, and the upper ones with a slight shift of the router in favor of experts already in memory: in the 80B model, 0.5% paraflexia increases. The measurements were performed in the context of 1,024 tokens on responses of 160 tokens each. On the Xiaomi set-top box and the iPad Air 2013, where no more than 1GB is available for the program, the same techniques are used to launch Model 16B Ling-mini-2.0 speeds in the graph.

This is a llama.cpp update to MoE: some of the expert advisors are in memory, the rest are called from a flash drive when the router selects them, and the next layer's expert advisors are preloaded. Everything is calculated on the processor, on Android without root.

The experts were compressed to 2 bits, and the long answers were looped: according to the authors' measurements, the repetition penalty reduced the number of looped answers from 12 out of 13 to 1 out of 13. Phone-ready files can also be opened by regular llama.cpp, but only a patched build delivers the claimed speeds. Colleagues have analyzed in more detail how the replacement of the expert advisor works.

More on Radar

Want to see every report in real time?

Hundreds of sources worldwide, translated into your language, with alerts for what matters to you.

Sign up free
Share on WhatsApp Get alerts on Telegram