Radar Telegram alerts Open Radar

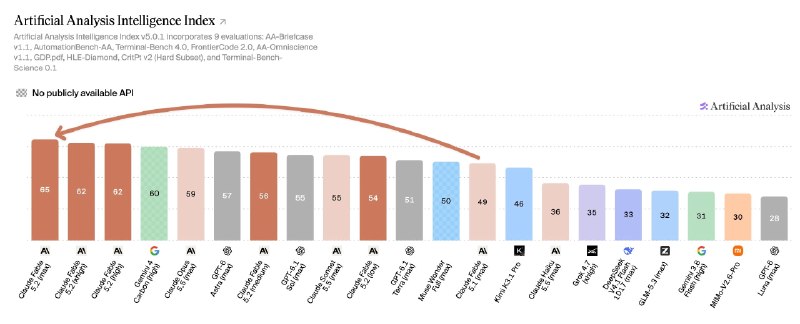
Artificial analysis put the Claude Fable 5.2 through its benchmark: 65 points and first place, 5 above the Gemini 4 Carbon and 6 above the Opus 5.5.

תרגם לעברית

Нейроканал (RU) · · Source

Artificial analysis put the Claude Fable 5.2 through its benchmark: 65 points and first place, 5 above the Gemini 4 Carbon and 6 above the Opus 5.5.

Artificial analysis put the Claude Fable 5.2 through its benchmark: 65 points and first place, 5 above the Gemini 4 Carbon and 6 above the Opus 5.5.

The model is the strongest in science and knowledge. There is no gap in the performance of the agents: in Terminal-Bench 4.0 it has the same 60% as Opus 5.5, and Kimi K3.1 Pro, Gemini 4 Carbon and Sonata 5.5 are ahead.

Max Mission costs $26.5, 2.6 times more expensive than opus 5.5. High is more profitable: 62 points, more than any other model, and about $9 per mission. Colleagues took a closer look.

More on Radar

Want to see every report in real time?

Hundreds of sources worldwide, translated into your language, with alerts for what matters to you.

Sign up free
Share on WhatsApp Get alerts on Telegram