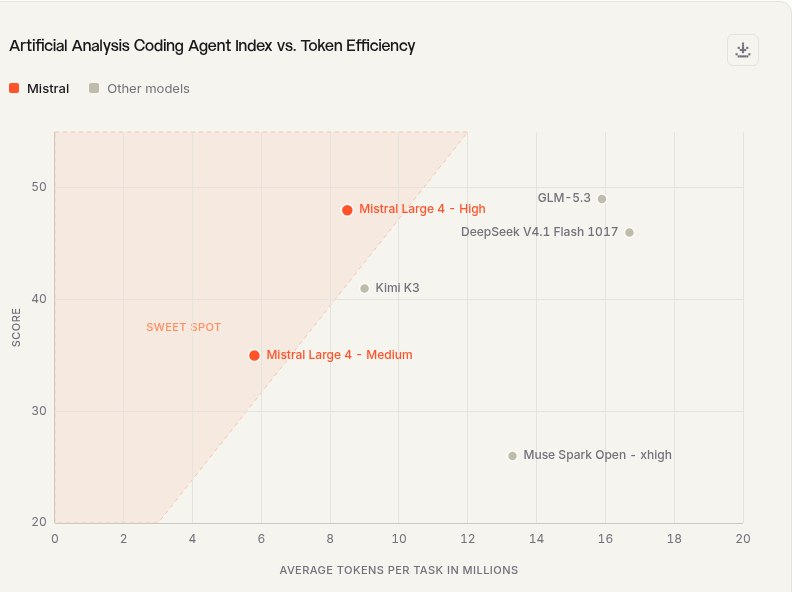
Mistral published the 4 big weights, aka Le Chunk. After the preview, the model underwent further training for three more weeks with reinforcement, and the company presented measurements of artificial analysis in the announcement: in Terminal-Bench 4.0 the new version had 41%, the best result among the models with open weights, and the preview, based on Mistral's own measurements, got 28%. In the high-state coding agent index, it nearly catches up with the GLM-5.3, 48% vs. 49%, and produces an average of 47% fewer tokens per task. The dumbbells were released under a different MIT: the model can be used and trained later in commercial products; A separate license is required for companies providing access to a service model. Within MoE, 49 billion are active out of a trillion parameters, the context of a million tokens. Not lazy already GGUF compilation, the most compressed quantum weighs 233 GB. In the API the price is $0.70 per million input tokens and $2.10 per million output tokens, almost the same as the discounted preview I wrote about.
Mistral published the 4 big weights, aka Le Chunk. After the preview, the model underwent further training for three more weeks with reinforcement, and the company presented measurements of artificial analysis in the announcement: in Terminal-Bench 4.0 the new version had 41%, the best result among the models with open weights, and the preview, based on Mistral's own measurements, got 28%. In the high-state coding agent index, it nearly catches up with the GLM-5.3, 48% vs. 49%, and produces an average of 47% fewer tokens per task. The dumbbells were released under a different MIT: the model can be used and trained later in commercial products; A separate license is required for companies providing access to a service model. Within MoE, 49 billion are active out of a trillion parameters, the context of a million tokens. Not lazy already GGUF compilation, the most compressed quantum weighs 233 GB. In the API the price is $0.70 per million input tokens and $2.10 per million output tokens, almost the same as the discounted preview I wrote about.
More on Radar
Want to see every report in real time?
Hundreds of sources worldwide, translated into your language, with alerts for what matters to you.
Sign up free Already have an account? Log in