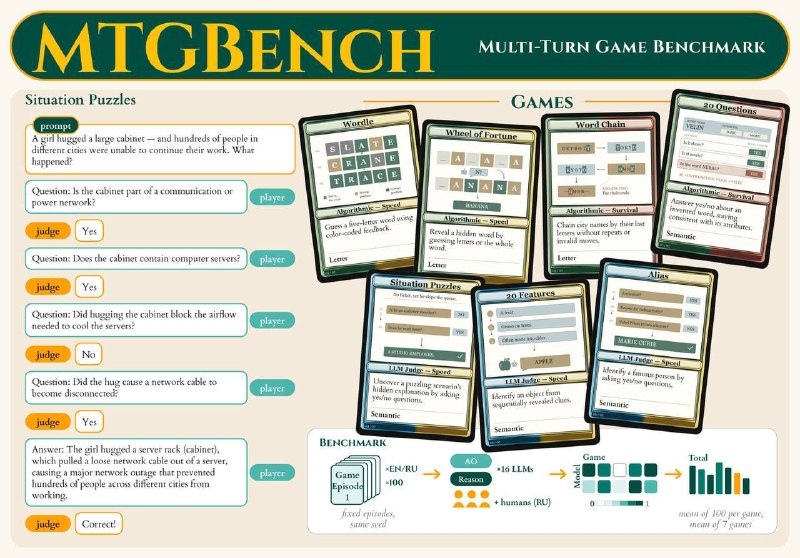
Now you can test the logic of neural networks in a new way - students of Sh. d and Yandex researchers published the MTGBench benchmark, which helps evaluate how different models cope with multi-step tasks and how thinking affects their results. Inside are seven text games in Russian and English. Among them: "Dantaki", "Kinoy", Wardel, "Sde Nissim" and others. It turned out that logic helped more prominently in tasks with letters and symbols. In tasks on knowledge and understanding of meaning, the effect was less pronounced and depended on the model. An article on MTGBench was published in Findings of EMNLP 2026. SHAD students became co-authors of international research during their studies. The code, tasks, and results are on GitHub.
Now you can test the logic of neural networks in a new way - students of Sh. d and Yandex researchers published the MTGBench benchmark, which helps evaluate how different models cope with multi-step tasks and how thinking affects their results. Inside are seven text games in Russian and English. Among them: "Dantaki", "Kinoy", Wardel, "Sde Nissim" and others. It turned out that logic helped more prominently in tasks with letters and symbols. In tasks on knowledge and understanding of meaning, the effect was less pronounced and depended on the model. An article on MTGBench was published in Findings of EMNLP 2026. SHAD students became co-authors of international research during their studies. The code, tasks, and results are on GitHub.
🇷🇺 Russia · Map
More on Radar
Want to see every report in real time?
Hundreds of sources worldwide, translated into your language, with alerts for what matters to you.
Sign up free Already have an account? Log in