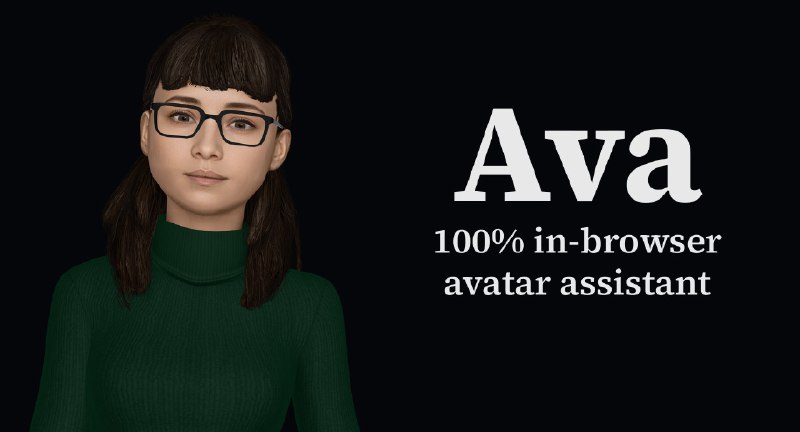
Ava: full native and real 3D avatar on WebGPU with TalkingHead and LFM3-Omni-2B No H100 and cloud intervention. Payback is an uncanny valley of hell that will survive 3D for the rest of its technological life. It's just elegant open source crap and very easy in terms of implementation, so I'll leave it here. You can play yourself now. Tags: Hogging Face Spaces The data stream goes directly through three local links: sound from the microphone cuts the Silero VAD (WASM), then audio without an intermediate STT cloud is fed to the LFM3-Omni-2B (built on the basis of the LFM3-1.7B, produces both text and speech), and the 3D-lipsin engine is responsible for the TalkHead. It directly compares the phone sequence that the model repeats, rigidly synchronizing the articulation with the synthesized voice. At the level of WebGPU-runtime (Chrome / Edge), three optimizations are used at once: extension of Shadowr-f16 for FP16-matrix calculations, reduction of a separate WebWorker (so as not to drop FPS 3D scenes) and chank to load 1.6 GB of GGUF weight with caching in the browsers index. DB. For emotions and gestures, the src/reactions.js module (semantic map of text in frequency, swing and fingers), when interrupted (barge-in), only the actual voice part of the answer falls into the story, and the system makes quick changes on the fly without renewing the scales. The main trade-off is the intentional abandonment of the 70B+ cloud assistants for privacy and zero network latency. Lipsync and 3D: TalkingHead rectifies the phone stream from the LFM3-Omni-2B and lip syncs in speech. WebGPU stack: 1.6GB quantum GGUF in IndexedDB (Chank's sand), Shadowr-f16 (FP16) and no blocking WebWorker. Interactive: barge-in with stories about lost audio, reactions in src/reactions.js and a quick change hot system. Compromise: compact 2B parameters instead of heavy oil 70B + models for full local on the device.
Ava: full native and real 3D avatar on WebGPU with TalkingHead and LFM3-Omni-2B No H100 and cloud intervention. Payback is an uncanny valley of hell that will survive 3D for the rest of its technological life. It's just elegant open source crap and very easy in terms of implementation, so I'll leave it here. You can play yourself now. Tags: Hogging Face Spaces The data stream goes directly through three local links: sound from the microphone cuts the Silero VAD (WASM), then audio without an intermediate STT cloud is fed to the LFM3-Omni-2B (built on the basis of the LFM3-1.7B, produces both text and speech), and the 3D-lipsin engine is responsible for the TalkHead. It directly compares the phone sequence that the model repeats, rigidly synchronizing the articulation with the synthesized voice. At the level of WebGPU-runtime (Chrome / Edge), three optimizations are used at once: extension of Shadowr-f16 for FP16-matrix calculations, reduction of a separate WebWorker (so as not to drop FPS 3D scenes) and chank to load 1.6 GB of GGUF weight with caching in the browsers index. DB. For emotions and gestures, the src/reactions.js module (semantic map of text in frequency, swing and fingers), when interrupted (barge-in), only the actual voice part of the answer falls into the story, and the system makes quick changes on the fly without renewing the scales. The main trade-off is the intentional abandonment of the 70B+ cloud assistants for privacy and zero network latency. Lipsync and 3D: TalkingHead rectifies the phone stream from the LFM3-Omni-2B and lip syncs in speech. WebGPU stack: 1.6GB quantum GGUF in IndexedDB (Chank's sand), Shadowr-f16 (FP16) and no blocking WebWorker. Interactive: barge-in with stories about lost audio, reactions in src/reactions.js and a quick change hot system. Compromise: compact 2B parameters instead of heavy oil 70B + models for full local on the device.
More on Radar
Want to see every report in real time?
Hundreds of sources worldwide, translated into your language, with alerts for what matters to you.
Sign up free Already have an account? Log in